In more than a decade maintaining production Linux environments and cloud infrastructures, I have rarely witnessed financial waste as severe as continuously paying for dedicated GPU instances serving intermittent traffic.
Many engineering teams provision a GPU virtual machine. On Lambda's price list, checked in October 2026, an H100 costs $3.29 to $4.29 per GPU-hour and an A100 costs $1.99 to $2.79. If your application only serves clients during business hours — 8 hours on weekdays —, the card sits idle for roughly three quarters of the month's 730 hours. Kept powered 24/7, an H100 at $3.99/hour costs close to $2,900 a month; an 80 GB A100, around $2,040.
To address this structural cost inefficiency, DigitalOcean launched its GenAI Platform (now renamed DigitalOcean Inference), anchored by the DigitalOcean GenAI Inference Engine and Serverless Inference.
In this technical guide, I evaluate the architectural foundations of DigitalOcean's AI ecosystem, the mechanics of the Inference Router (powered by the Plano proxy layer), how to integrate workloads using drop-in OpenAI-compatible SDKs, and how to operate resilient AI pipelines without paying for idle GPUs.
1. The Infrastructure Dilemma: Dedicated GPUs vs. Serverless Inference#
When designing deployment architectures for AI agents and RAG pipelines across my environments, I evaluated three classical market approaches:
- Direct Proprietary APIs (OpenAI / Anthropic): Straightforward to consume over HTTP, but vulnerable to per-token pricing updates, restrictive rate-limits, and vendor lock-in.
- Self-Hosted Dedicated GPUs (vLLM / Ollama on GPU VPS): Grants complete sovereignty over open-weights models (Llama 3, DeepSeek, Mistral), but incurs steep round-the-clock expenses, demands complex CUDA driver orchestration, and cannot scale to zero.
- Serverless Inference Platforms: You are billed strictly for generated tokens or active fractions of execution time. When no incoming traffic exists, compute costs drop precisely to zero.
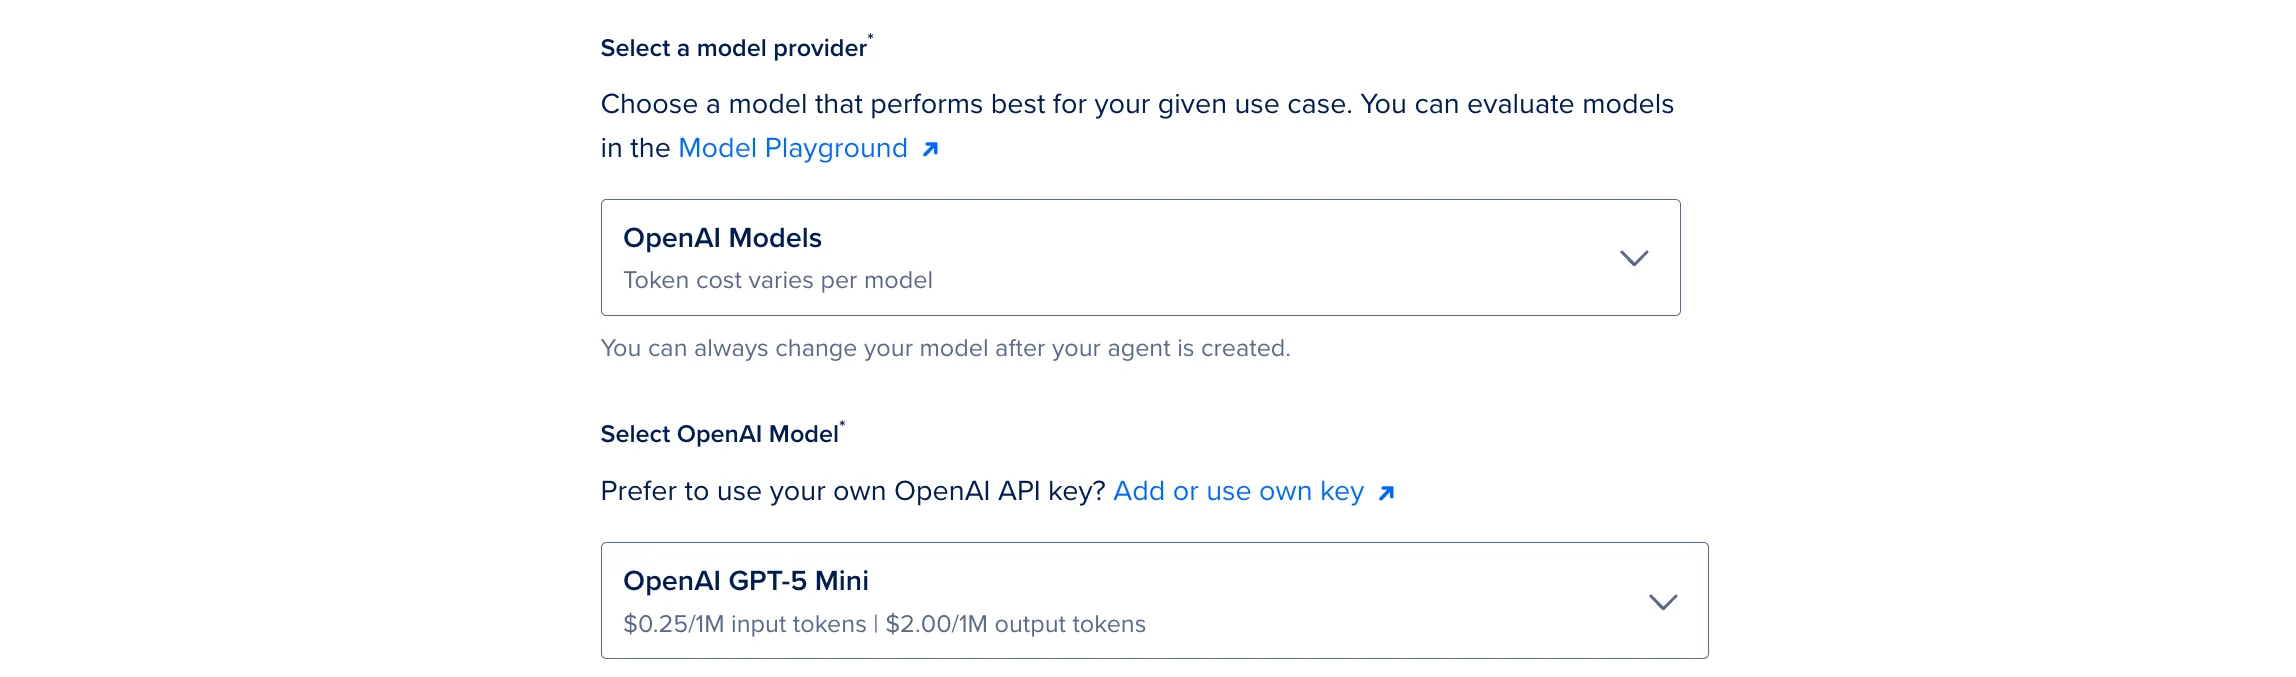
DigitalOcean Serverless Inference bridges these paradigms: top-tier open models (today's catalog lists Llama 4 Maverick, DeepSeek V3, and the Mistral family, among more than 70 models) hosted across managed elastic infrastructure, accessible through standardized APIs with pay-per-token utility billing.
2. DigitalOcean GenAI Architecture: Control Plane and Data Plane#
The platform cleanly decouples governance from high-throughput execution:
┌─────────────────────────────────────────────────────────────┐
│                 Client Applications & Agents                │
│             (Web Apps, Support Bots, Automations)           │
└──────────────────────────────┬──────────────────────────────┘
                               │ OpenAI-Compatible API
                               ▼
┌─────────────────────────────────────────────────────────────┐
│             DigitalOcean Inference Router (Plano)           │
│  - Fast Intent Resolution (~200ms)                          │
│  - Balancing Policies: Cost vs. Latency vs. Quality         │
│  - Automated Fallback Chains                                │
└──────────────┬───────────────────────────────┬──────────────┘
               │                               │
               ▼                               ▼
┌──────────────────────────────┐ ┌────────────────────────────┐
│    Serverless Inference      │ │    Dedicated Inference     │
│  - Meta Llama 3 / DeepSeek   │ │  - Private GPU Clusters    │
│  - Open-Source Models        │ │  - Custom Model Adapters   │
│  - Pay-per-Token Model       │ │  - Guaranteed Throughput   │
└──────────────────────────────┘ └────────────────────────────┘
Architectural Breakdown:#
- Control Plane: Governs workspaces, token access keys scoped to least privilege (
genai:read,genai:create), spending quotas, and catalog selections. - Inference Engine (Data Plane): The underlying runtime executing model calculations. Accommodates real-time serverless inference, Dedicated Inference (dedicated GPUs for high-volume workloads), and asynchronous batch jobs.
- Agent & RAG Platform: Managed pipeline enabling direct ingestion of unstructured documents (PDF, DOC, CSV, or live web crawlers) to dynamically supply vector retrieval context prior to model generation.
3. Intelligent Traffic Routing: The Inference Router#
A standout technical asset within the ecosystem is the Inference Router, currently in public preview and built on Plano, the open-source proxy created at Katanemo — a company DigitalOcean acquired in April 2026. DigitalOcean's own architecture post describes the routing model that resolves intent in roughly 200 ms.
Rather than embedding fragile conditional routing in your application layer (e.g., if prompt_length > 2000: use_large_model()), applications target a unified virtual endpoint.
The Inference Router acts as an intelligent edge reverse proxy:
- Sub-Second Intent Resolution (~200ms): A specialized dense model inspects prompt context and incoming task complexity.
- Policy Balancing: Operators designate whether execution targets Lowest Cost, Lowest Latency, or Peak Quality. Lightweight categorization requests route to efficient models (e.g., Llama 3 8B), while intricate reasoning cascades to frontier LLMs.
- Ordered Fallback Chains: In the event that a primary model experiences transient capacity constraints or upstream latency degradation, requests automatically reroute to secondary models without returning HTTP errors to end users.
3.1 What Changed in 2026: Plano-Orchestrator, Presets, and the Katanemo Acquisition#
The router in production is no longer a generic rule-based proxy: routing is handled by Plano-Orchestrator, a model trained specifically to detect the task in a conversation. It ships in two variants — a 4B dense model for latency-sensitive deployments and a 30B-A3B Mixture-of-Experts model for higher accuracy. In DigitalOcean's published evaluation across 1,958 messages in 605 multi-turn conversations, the 30B-A3B model scored 87.84% average accuracy, ahead of GPT-5.1 (86.93%) and Claude Sonnet 4.5 (86.11%).
In practice you don't configure a model per case: pick a preset (Software Engineering, General, Writing, or Knowledge Base & Document Intelligence) or build a custom router through the API, set the policy — Optimal, Cost Efficiency, or Speed Optimization — and point your app at router:<name>. The response tells you which model served the request and which task matched (the x-model-router-selected-route header); if nothing matches, the configured fallbacks are tried in order.
4. Hands-on Implementation: Consuming the API via Python and cURL#
DigitalOcean adopted complete compatibility with the OpenAI Chat Completions specification. Migration requires updating your endpoint base_url and inserting your workspace access key.
Example 1: Command-line Execution via cURL#
curl -X POST "https://inference.do-ai.run/v1/chat/completions" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $DO_GENAI_API_KEY" \
  -d '{
    "model": "llama-4-maverick",
    "messages": [
      {
        "role": "system",
        "content": "You are a Linux systems engineer and cloud infrastructure architect."
      },
      {
        "role": "user",
        "content": "What kernel sysctl parameters optimize network socket memory for high concurrency?"
      }
    ],
    "temperature": 0.3,
    "max_tokens": 512
  }'
Example 2: Python Integration with Official OpenAI Client#
import os
from openai import OpenAI

# Initialize client pointing to DigitalOcean's inference proxy
client = OpenAI(
    base_url="https://inference.do-ai.run/v1",
    api_key=os.environ.get("DO_GENAI_API_KEY")
)

response = client.chat.completions.create(
    model="router:software-engineering",
    messages=[
        {"role": "system", "content": "Infrastructure troubleshooting assistant."},
        {"role": "user", "content": "Analyze log: nginx 502 Bad Gateway - connect() to php-fpm.sock failed (11: Resource temporarily unavailable)"}
    ],
    temperature=0.2,
)

print(response.choices[0].message.content)
In the Python implementation above, specifying "model": "router:software-engineering" delegates model selection entirely to the DigitalOcean Inference Engine.
5. Economic Breakdown: Dedicated GPU Node vs. Serverless Inference#
To quantify the operational impact, consider the financial trajectory of a growing SaaS product processing variable daily requests:
| Operational Metric | Dedicated Inference (1× AMD MI300X) | DigitalOcean Serverless Inference |
|---|---|---|
| Idle Monthly Baseline | ~$1,890 / month ($2.59/hour × 730 h) | $0.00 |
| Active Compute (Business Hours) | 8 hours/day active compute | Pay strictly for processed tokens |
| Off-Peak (Nights & Weekends) | Charges 100% flat rate | Zero charges |
| Driver & CUDA Maintenance | Sysadmin overhead (patches, crashes) | Fully managed by cloud provider |
| Concurrency Spike Handling | Out-of-memory (OOM) crash risk | Instantaneous elastic scaling |
| Multi-Model Support | Constrained by local physical VRAM | Instant access to multi-model catalog |
In the table's scenario, where the GPU only works during business hours, roughly three quarters of the month's hours are idle — and that is the share of the bill token-based billing removes. In the opposite direction, if your volume keeps the GPU busy nearly all the time, a dedicated endpoint billed by the hour tends to cost less than tokens.
5.1 What the Inference Bill Actually Charges#
It helps to separate the four billing lines, because each one reacts differently to the same traffic:
- Serverless Inference: priced per 1 million tokens, published per model, and billed prepaid — no request, no charge.
- Dedicated Inference: billed per GPU-hour whether traffic exists or not. On the official table: AMD MI300X $2.59/h; MI325X $2.98/h; NVIDIA H100 $4.41/h; H200 $4.47/h; B300 $10.39/h (multi-GPU sets have their own price, such as 8× MI300X at $20.70/h).
- Batch Inference: up to 50% off OpenAI and Anthropic model rates, charging only completed requests.
- Inference Router: no additional cost during public preview; you pay only for the tokens of the model that served the call.
That is the difference between renting the card and renting the result. For intermittent traffic, the second column wins; for steady, predictable flow, a dedicated GPU can still be cheaper per token — and you can now compare both on the same bill.
6. Security Governance and Best Practices#
When integrating cloud LLM services into production stacks, security governance must remain front and center:
- Scoped Access Tokens: Generate dedicated tokens limited strictly to inference tasks (
dedicated_inferenceor read-only serverless execution), preventing exposure of root management keys capable of altering Droplets or block storage. - RAG Knowledge Isolation: According to the Inference data privacy documentation, DigitalOcean does not use customer prompts or uploaded documents to train, retrain, or fine-tune generalized models. The caveats are Signals (an optional tracing feature) and third-party models, which follow the original provider's retention policy.
- Usage Threshold Alerts: Establish automated billing thresholds within the DigitalOcean dashboard to monitor token consumption rates and eliminate end-of-month budget surprises.
7. The Sysadmin Verdict: When Should You Adopt DigitalOcean Inference?#
Migrate immediately if:#
- You deploy open-weights models (Llama, DeepSeek, Mistral) and want to stop paying for idle GPU capacity.
- Your application experiences bursty, irregular request patterns.
- You prefer standard OpenAI SDK conventions without maintaining Kubernetes clusters or custom Triton/vLLM containers.
- You require automated model routing and fallback redundancy for enterprise availability.
7.1 Migration Checklist#
- Measure first: export token consumption per day or week from your current provider (or estimate it from request logs). Without that number, any comparison is a guess.
- Test the preset before the code: run a preset router in the Playground and compare cost and latency per request against the single model you use today.
- Load prepaid credit: serverless inference is prepaid; without balance or credits, requests are suspended.
- Set policy per route: cost for classification and summarization, quality for reasoning, latency for real-time support.
- Only then consider dedicated: if the GPU stays busy for most of the month, the hourly endpoint ($2.59/h on MI300X) enters the math as an alternative, not as the default.
Developers evaluating managed AI infrastructure can test live endpoints directly on DigitalOcean.
8. Frequently Asked Questions (FAQ)#
Can I drop this into existing OpenAI-based codebases?#
Yes. DigitalOcean mirrors standard Chat Completions payloads. Update the client base_url to https://inference.do-ai.run/v1 and supply your model access key across official Python, Node.js, Go, or PHP libraries.
Are customer prompts used to train DigitalOcean foundation models?#
No. The Inference data privacy documentation states that DigitalOcean does not use customer content to train generalized models and does not send it back to the model's creator. The caveats are third-party models you connect yourself and Signals (optional), which follow the provider's retention terms.
What distinguishes Serverless Inference from Dedicated Inference?#
Under Serverless Inference, requests execute over managed elastic compute pools billed per token, scaling to zero when idle. With Dedicated Inference, GPUs are reserved solely for your organization, providing deterministic hardware throughput for sustained enterprise workloads.
Was this article helpful?
Leave a quick reaction to help prioritize future technical guides:
See also

This post is licensed under CC BY-NC.
Comments
Join the discussion below.
0 comments